Data quality management (DQM) is the ongoing practice of defining, measuring and improving data so it is fit for its intended use. It combines business rules, profiling, cleansing, validation, ownership and monitoring. In this guide, DIGI-TEXX explains the six commonly used quality dimensions, a six-step management process and practical ways to measure progress. [1][2]
A useful program does more than correct a spreadsheet once. It identifies why defects occur, assigns someone to resolve them and checks whether the next batch improves. Start with a business problem—such as duplicate customer records or incomplete invoice fields—then define the evidence needed to accept the data.
>> See more:
- Intelligent Document Processing Services: How It Works & Business Benefits
- How To Prepare a Classified Balance Sheet: Template & Example
- Business Process Automation Solutions: Benefits, Example & Service Company
- What Is Business Process Outsourcing (BPO)? Definition & Benefits
What is Data Quality Management?
Data quality management turns a general expectation of “good data” into documented rules, accountable roles and repeatable checks. It covers data as it is collected, transformed, shared and used, with attention to the decisions or operations that depend on it. The UK Government Data Quality Framework describes quality in terms of fitness for purpose and emphasizes improvement at the source. [1]
For example, a customer address may be complete and follow a valid postal format but still belong to the wrong person. A sales report can contain accurate individual values while omitting an entire region. DQM therefore needs several checks, not a single “accuracy” score.
The scope should identify the data domain, source systems, business use, critical fields and accountable owner. A daily fulfillment feed and an annual historical report may need different freshness targets. Good quality is contextual; a perfect-looking file is not automatically suitable for every use.
Six Dimensions of Data Quality Management
A commonly used model evaluates accuracy, completeness, consistency, timeliness, uniqueness and validity. These dimensions describe different problems; they should not be treated as interchangeable. The table below provides illustrative business checks rather than universal acceptance thresholds. [2]
| Dimension | What to test | Illustrative check |
| Accuracy | Agreement with a trusted reference | Customer ID belongs to the intended account. |
| Completeness | Presence of required records/fields | Every order has its required delivery field. |
| Consistency | Agreement under shared definitions | Customer status agrees across systems at the same cutoff. |
| Timeliness | Availability within the required interval | A daily feed arrives before the reporting cutoff. |
| Uniqueness | No unintended repeated entities/records | Duplicate customer candidates are reviewed under an agreed rule. |
| Validity | Conformance to allowed formats and rules | A product code belongs to the approved reference list. |
Validity does not establish accuracy: a date can use the correct format but describe the wrong event. Completeness also needs a defined scope; an optional field should not fail a required-field check. Document which records, fields and exceptions are included in each measure.
Dimensions Of Data Quality Management
Effective data quality management ensures that an organization’s data aligns with the 6 dimensions of data quality:
- Accuracy: Ensures data correctly represents real-world events and values by identifying and correcting errors or misrepresentations.
- Completeness: Achieved when a dataset contains all necessary records without gaps or missing values.
- Consistency: Ensures data is coherent and standardized across different datasets, making them compatible with each other.
- Timeliness: Measures how up-to-date data is, preventing decisions based on outdated information.
- Uniqueness: Refers to the absence of duplicate or redundant data, which could distort analysis.
- Validity: Ensures data adheres to business rules, such as conforming to specified ranges or format standards.
>>> See more:
- Construction Invoice Reconciliation: Best Practices, Software & Outsourcing
- The Ultimate Guide to Address Validation Software
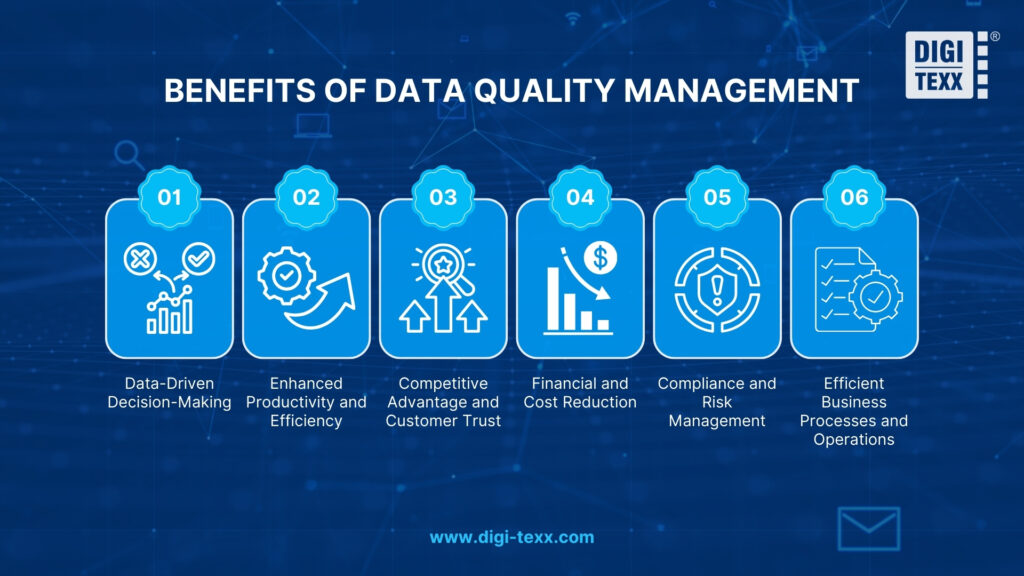
Benefits of Data Quality Management
The value of DQM is best demonstrated through fewer operational defects and more dependable information. Keep the original six benefit areas, but measure their contribution against a baseline instead of assuming that a quality initiative guarantees a business outcome.
1. Data-Driven Decision-Making
With effective data quality management practices, organizations can confidently make business decisions based on trustworthy and high-quality data. When data teams can trust the organization’s data landscape, it leads to increased data utilization and promotes a culture of data-driven decision-making.
Inaccurate or obsolete data can result in mistakes and flawed decision-making, while robust data quality management establishes a reliable foundation for strategic planning and operational excellence across all business activities.
Clear definitions and reconciled inputs make reports easier to interpret. When figures disagree, an owner and source trail help analysts investigate the difference before it informs a decision. Track recurring reconciliation issues and unresolved limitations, as well as dashboard availability.
2. Enhanced Productivity and Efficiency
Data quality management ensures that organizations handle data quality issues in an automated and augmented manner, reducing manual intervention and errors. Automation practices significantly reduce the time taken to identify and resolve data quality issues, allowing employees to spend less time dealing with data errors and more time focusing on their core data management tasks and strategic initiatives.
Repeatable checks can reduce time spent finding the same missing fields or format errors. Human reviewers can focus on ambiguous cases instead of rechecking every clean record. Compare correction time and exception workload before and after implementation.
3. Competitive Advantage and Customer Trust
High-quality data plays a crucial role in ensuring that businesses maintain a strong reputation and gain a competitive advantage in the marketplace. Organizations with reliable data can deliver better customer experiences, more accurate products and services, and build lasting trust with their stakeholders.
Conversely, poor data quality has been proven to bring about customer distrust and dissatisfaction, potentially damaging brand reputation and market position. Companies that prioritize data quality management are better positioned to outperform competitors and maintain customer loyalty.
Consistent customer and product records can support clearer communication, fewer misdirected messages and fewer contradictory descriptions. The effect on trust depends on the wider experience. Track actual contact errors, product-data complaints or avoidable service corrections.
4. Financial and Cost Reduction
Duplicate supplier records, incorrect quantities and mismatched identifiers can create rework or payment exceptions. DQM can help identify these issues earlier. Evaluate avoided rework and documented corrections against the cost of software, review and ongoing stewardship. Accurate and up-to-date data offers a clear view of daily operations, ensuring confidence in both upstream and downstream applications.
5. Compliance and Risk Management
Documented quality controls can support reporting and review requirements by making data more traceable. They do not independently establish legal compliance. Separate quality checks from access controls, privacy requirements and the legal assessment appropriate to your organization. Organizations avoid substantial penalties, legal issues, and brand damage by translating governance policies into actionable database-level practices.
6. Efficient Business Processes and Operations
Reliable data streamlines business processes across all departments, enabling faster reporting, improved collaboration, and better system integration. When data flows seamlessly and accurately, teams work more effectively, make timely decisions, and respond quickly to changing business conditions.
Agreed identifiers, field definitions and formats make transfers between systems easier to manage. Test both the data and its use at the destination: a file can pass a format check while mapping a customer to the wrong account. Monitor rejected imports and downstream incidents.
>>> See more:
- What Is A Back Office Service? Examples, Benefits, And Cost In 2026
- Top 10 Outsourced AI Training Data Companies in 2026
- What Is Data quality control? Key Components, Tools & Examples
Data Quality Management Process: Six Steps
The process below expands the original six steps into an operational framework. Assign an accountable owner at the start, then repeat assessment, remediation and monitoring as data changes. The order is a practical guide, not a requirement to delay governance until the final step.
1. Define Quality Standards and Business Rules
Start with the decision or process at risk. Identify critical fields and write rules in language that both business and technical teams can test. Specify the source of truth, refresh expectation, excluded records and the action required when a rule fails.
- Output: a rule register with a rule ID, scope, owner, threshold, severity and review frequency.
2. Profile and Assess Current Data
Profile types, nulls, value distributions, duplicates and relationships before making changes. Break results down by source, period or business unit to avoid hiding a weak segment inside an acceptable average. Use profiling to find questions; verify suspected errors against a trusted reference.
- Output: a baseline scorecard and a prioritized issue list, including the population or sample tested.
3. Cleanse and Standardize Data
Apply approved transformations such as trimming unwanted spaces, standardizing date representations or correcting verified values. Preserve identifiers with leading zeros. Route uncertain matches and conflicting values to a reviewer instead of silently choosing or inventing a replacement.
- Output: corrected data, a transformation log, source identifiers and an exception queue.
4. Validate Data Against Rules
Run the rules after remediation and at relevant entry or transfer points. Check relationships as well as individual fields—for example, whether a line item belongs to a known order. Reconcile input and output counts, explaining authorized merges, splits and rejected records.
- Output: test results, reconciliation totals and an acceptance decision by the designated owner.
5. Monitor and Control Continuously
Schedule checks to match business risk and update frequency. A daily batch may need a daily check; a time-sensitive feed may need faster alerts. Give each alert an owner, severity and response expectation. Compare new incidents with the baseline and investigate recurring failures.
- Output: a monitored scorecard, incident history and root-cause actions with due dates.
6. Establish Governance and a Data Quality Culture
Maintain ownership, approval rights and shared definitions as part of everyday work. Data owners decide what is acceptable; stewards coordinate definitions and issues; engineers implement controls. Business users report problems and confirm whether the data serves the intended task.
- Output: assigned responsibilities, a change process and periodic reviews of rules and unresolved risks.
>>> See more:
- Top 10 Data Cleansing Companies for Businesses
- What are the 6 steps of the data analysis process?
The Impact of AI and Automation on Data Quality Management
Automation is useful for repeatable tests and transformations. AI can assist with anomaly detection and potential entity matches, but an unusual value is not necessarily wrong. IBM describes AI and automation as part of the evolving DQM toolset; the appropriate controls still depend on the task and data. [3]
- Use deterministic rules for known constraints, such as allowed codes or required identifiers.
- Use models to flag candidates where patterns are complex, such as probable duplicate names.
- Review uncertain or high-impact changes before they overwrite source data.
- Evaluate false positives, missed defects and reviewer workload against a labeled test set.
- Keep versioned rules, transformation logs and a way to reverse approved changes.
Do not fill missing factual values with plausible AI-generated guesses. If the source cannot establish a value, retain an explicit unknown or exception status. Test new models on representative data before expanding their authority to change records.
>>> See more:
- Top 10 Data Entry Outsourcing Companies to Hire in 2026
- Outsourced data annotation services: List of best companies to work for
Data Quality Metrics: A Worked Example
Consider an illustrative batch of 1,000 customer records. The figures below are invented to demonstrate the calculations; they are not DIGI-TEXX client results. Each metric has its own denominator and test definition.
| Metric | Illustrative calculation | Interpretation |
| Required-field completeness | 960 / 1,000 × 100 = 96% | 40 records lack the required field. |
| Format validity | 980 / 1,000 × 100 = 98% | 20 values fail the defined format rule. |
| Excess duplicate-row rate | 40 / 1,000 × 100 = 4% | 40 rows beyond the first retained row per confirmed entity. |
| Timely-update rate | 900 / 1,000 × 100 = 90% | 100 records fall outside the agreed freshness interval. |
| Sampled-record accuracy | 95 / 100 × 100 = 95% | 95 sampled records match the reference on all checked critical fields. |
The accuracy check covers only 100 reviewed records, so its 95% result must not be reported as a verified accuracy score for all 1,000. Likewise, 40 excess duplicate rows does not mean exactly 40 duplicate groups. Report the matching rule and how many valid entities remain after approved merges.
Track critical defects separately from aggregate pass rates. A record with a wrong account association may warrant escalation even if the batch is nearly complete. If a composite score is used, disclose its weights and keep the underlying metrics visible.
Data Quality Management vs. Governance, Cleansing and MDM
These disciplines overlap but solve different parts of the problem. Assigning each a clear role helps prevent a cleanup project or a software purchase from being mistaken for an entire quality-management program.
- Data governance: establishes decision rights, policies and accountability.
- Data quality management: defines, measures, improves and monitors fitness for a specific use.
- Data cleansing: corrects or standardizes records as one activity within DQM.
- Data validation: tests whether data meets specified rules; it does not prove every value is true.
- Master data management (MDM): manages shared core entities such as customers or products and their relationships across systems.
11 Data Quality Management Best Practices
Use these practices to keep a quality program operational after the first cleanup. They retain the original article’s 11 areas while making the actions and responsibilities more explicit.
- Secure business sponsorship: connect the work to a defined operational problem and fund ongoing maintenance.
- Define measurable metrics: document denominators, exclusions, thresholds and critical-field failures.
- Implement governance: give named owners authority to approve rules and resolve conflicting sources.
- Create an issue-reporting channel: capture the affected record, source, business impact and reporter.
- Investigate root causes: distinguish a one-off correction from a problem in a form, integration or upstream process.
- Audit regularly: test representative edge cases and review whether accepted exceptions remain appropriate.
- Train contributors: explain field definitions, required evidence and how to report uncertain values.
- Maintain security controls: manage authorized access and change permissions alongside quality controls.
- Assign stewards: define practical responsibilities and escalation routes for each important data domain.
- Assess cloud automation deliberately: consider integration, access, monitoring and operating costs before selecting a platform.
- Automate stable integrations: add validation and reconciliation at handoffs, and regression-test rule changes.
Data Quality Tools and Platforms
The original article lists ten categories, despite introducing eight. The categories below retain that coverage while distinguishing profiling, monitoring and assessment. One product may cover several capabilities; evaluate the required workflow rather than counting features.
Data Profiling Tools
Such tools assess the health and profile data set by its structure, content, relationships, and by metrics that test interlinking datasets’ as well as data patterns’ interrelationship with each other, including outlier and trend identification. This helps businesses identify gaps that need to be filled to make better, more reliable decisions.
Inspect nulls, formats, distributions and relationships to establish the starting condition. Ask whether profiles can be filtered by source and period, and whether results retain enough context to reproduce an investigation.
Data Cleansing Tools
Apply approved correction and standardization rules to selected records. Look for preview, reversible transformations and exception handling. Standardizing a format is useful, but it should not overwrite a conflicting factual value without evidence.
Data Matching and Deduplication Tools
These tools are created with special capabilities for identifying approximate matches and redundant data. By employing specific algorithms and designs, these tools promote accuracy and quality of work. This improves the data quality management process.
Identify exact or probable matches using business identifiers and selected attributes. Test both false merges and missed duplicates. Define survivorship rules and keep a record of which source values contributed to the accepted entity.
Data Validation Tools
Information as valuable as money – invalidated information can impact an organization financially, therefore, businesses must control data flowing through systems as concepts change each second.
The validation process ensures that specific rules are followed, confirming each data type, range, and format against business rules or validation criteria.
Check formats, ranges, required fields and relationships against explicit rules. Decide whether a failed record should be blocked, quarantined or delivered with a warning. Verify that rule failures can be traced to the affected source record.
>>> See more:
- Best Data Cleansing Outsourcing Companies for 2026
- Best Insurance Claims Processing Outsourcing BPO in the US 2026
Data Enrichment Tools
These tools augment existing datasets by pulling in extra information from external resources like public records or third-party providers. Enrichment aids in factually augmenting datasets to make them more complete, which in turn makes them more valuable for analytics and decision-making processes. See also: 11+ data enrichment tools
Add information from approved sources where that information is relevant and available for the intended use. Record provenance, match confidence and update date. An added field is not automatically accurate merely because it came from another system.
Data Governance and Data Quality Management Tools
Data Governance and Data Quality Management Tools creates strategic guidelines for data governance, which include policies, rules, quality frameworks, and stewardship procedures. They define accountabilities and responsibilities to ensure proactive corporate data quality management and compliance with relevant regulations.
Maintain definitions, rule ownership, approvals and issue workflows. Evaluate whether a business user can understand a rule and identify the responsible owner. A catalog entry without an active resolution process has limited operational value.
Data Monitoring and Profiling Tools
Data monitoring tools continuously observe data as it flows into and out of an organization. They detect quality issues in real time, sending alerts to enable immediate action and maintain consistent data quality.
Run ongoing checks for changing quality conditions, freshness delays or unexpected volumes. Evaluate alert routing, suppression and historical trends. Monitoring detects problems; it does not necessarily correct them.
Master Data Management (MDM) Tools
MDM tools create and maintain a unified, reliable source of master data across an organization. They ensure consistency and accuracy for critical data, such as customer, product, or employee information.
Maintain shared customer, supplier or product entities and distribute approved master records. Review entity resolution, hierarchy handling and merge reversal. A consolidated record still needs quality checks and accountable ownership.
>>> See more:
- An Overview of Document Processing Company: What You Need to Know
- Outsourcing Data Management: Benefits, Services & Best Practices
Data Quality Reporting and Dashboards
These tools provide visualization and reporting features to track and share data quality status. They deliver insights into metrics, trends, and areas needing improvement, supporting informed decision-making.
Display trends, rule failures and remediation status to different audiences. Include the tested population and important exclusions. A useful dashboard links a deteriorating metric to an owner and an action, not just a color.
Data Quality Assessment and Profiling Tools
These tools periodically or selectively evaluate data quality, helping organizations identify issues, assess dataset health, and prioritize efforts to enhance data quality and management.
Support periodic reviews or release decisions using documented checks and evidence. Unlike continuous monitoring, an assessment is bounded by a defined dataset or time. Retain the rule version, sample definition and acceptance outcome.
Before selecting a platform, run a pilot using your actual formats and known defects. Compare integration effort, testing coverage, human-review needs, auditability and total operating cost. This guide explains capability categories; it does not rank software or claim that a product has been hands-on tested.
See more: Data cleansing tools
See more: Data Cleansing Outsourcing Companies
See more: Insurance Claims Processing Outsourcing
See also: Data enrichment tools
See more: Data Quality Management Tools
See more: Document Processing Company
See more: Outsourcing Data Management
Common Data Quality Management Mistakes
A program can produce attractive metrics while leaving the underlying business problem unresolved. Review these failure modes when setting up controls and accepting corrected data.
- Treating valid formats as proof of factual accuracy.
- Deleting suspected duplicates without reviewing entity matches or keeping a merge trail.
- Fixing downstream records repeatedly while leaving the source defect unchanged.
- Reporting a sample result as a complete-population guarantee.
- Using a high average score to hide serious failures in a small critical segment.
- Assigning alerts to “the data team” without a named owner or response target.
FAQs About Data Quality Management
What Is The Purpose Of Data Quality Management?
Its purpose is to make data dependable enough for its intended use and to maintain that condition over time. DQM defines acceptable quality, identifies defects, coordinates corrections and prevents recurring problems.
What Are The Six Dimensions Of Data Quality?
A common model uses accuracy, completeness, consistency, timeliness, uniqueness and validity. Select checks and thresholds for the actual business use; the dimensions are not six interchangeable scores. [2]
How Do You Start A Data Quality Management Program?
Choose a specific business problem, identify critical fields and assign an owner. Profile a representative dataset, establish a baseline and test a small set of rules. Expand after confirming that corrections improve the intended workflow.
Does AI Enhance Data Quality Management?
AI can help flag anomalies or suggest matches, while rule-based automation handles known checks. It does not guarantee correct remediation. Evaluate performance on representative examples and require review before uncertain or high-impact changes.
What Are The 5 C’s Of Data Quality?
The original article uses completeness, consistency, conformity, correctness and currency as a five-C mnemonic. It should not be presented as a universal standard. This guide uses the explicitly sourced six-dimension model; if your organization uses the five C’s, document how each maps to its rules and measurements.
Which Industries Gain The Greatest Benefits From Data Quality Management?
Finance, healthcare, retail, manufacturing and telecommunications all depend on dependable records. The important questions are which decisions use the data and what a defect could affect. There is no single industry ranking established by this guide.
What is a good data quality score?
There is no universal passing score. Define acceptance by use, field importance and risk. Report critical defects separately, explain any composite weighting and state whether the result describes a full population or a sample.
Who Is Responsible For Data Quality?
Business data owners are accountable for requirements and acceptance. Stewards coordinate definitions and issue resolution; technical teams implement controls. Users and source-system teams help identify defects and address root causes.
Can Data Quality Management Be Outsourced?
Execution tasks such as cleansing, standardization and verification can be scoped for an external provider. Retain internal authority over business rules, permitted changes and acceptance. Confirm evidence, exception handling and the delivery format before production.
How DIGI-TEXX Can Support Data Quality Work
DIGI-TEXX’s data cleansing services describe cleanup, correction and database standardization. Its data verification offering includes checks on externally obtained or extracted information. These services can support defined parts of a DQM workflow; they do not replace your organization’s ownership of quality requirements and acceptance decisions. [4][5]
Share the data domain, source formats, critical fields, expected volume and known errors. Agree on a representative pilot, permitted transformations, exception reporting and the output your team can validate. Request project-specific capacity and quality commitments instead of treating company-wide headcount as reserved delivery capacity.
DIGI-TEXX’s About Us page lists ISO 27001:2022 and ISO 9001:2015 credentials. Confirm the current certificate scope for your engagement. These credentials concern management systems; they are not proof that every delivered field is correct. [6]
QTSC’s business directory lists DIGI-TEXX’s document and data-processing activities. This provides external context for its service presence, not independent evidence of a specific DQM accuracy rate or project outcome. [7]
Contact DIGI-TEXX to discuss data cleansing and verification requirements, review a representative sample and define a measurable acceptance process.
DIGI-TEXX Contact Information:
🌐 Website: https://digi-texx.com/
📞 Hotline: +84 28 3715 5325
✉️ Email: [email protected]
🏢 Address:
- Office 3: Innovation Solution Center, ISC Hau Giang, 198 19 Thang 8 street, Vi Tan Ward
- Headquarters: Anna Building, QTSC, Trung My Tay Ward
- Office 1: German House, 33 Le Duan, Saigon Ward
- Office 2: DIGI-TEXX Building, 477-479 An Duong Vuong, Binh Phu Ward
Referrences:
[1] UK Government — The Government Data Quality Framework
[2] UK Government Data Quality Hub — What is data quality?
[3] IBM — What Is Data Quality Management?
[4] DIGI-TEXX — Data Cleansing Services
[5] DIGI-TEXX — Data Verification Services
[7] QTSC — DIGI-TEXX Vietnam business directory
[8] Bing — Webmaster Guidelines